Run AI where your data lives.
EuLLM Engine is an open-source runtime for large language models. One Rust binary, OpenAI- and Ollama-compatible, zero telemetry. From a Raspberry Pi to an NVIDIA GH200 or an AMD Instinct MI250X.
Your models. Your infrastructure. Your data.
$ curl -fsSL https://raw.githubusercontent.com/eullm/eullm/main/installer/install.sh | sh
$ eullm run hf.co/Qwen/Qwen3-8B-GGUF:Q4_K_M
One runtime. One platform to build on it.
Engine runs models anywhere. Forge and Hub build and distribute the ones you specialize.
Engine
An open-source runtime for large language models. One binary, OpenAI- and Ollama-compatible, zero telemetry.
Read the Engine docs →Forge — specialize
Fine-tune, distill and evaluate open models on your data. Small specialists that answer precisely from your documents and sources, exported as a GGUF you own and run on Engine.
Explore the PlatformHub — distribute
Publish, version and discover models, each with a model card and a compliance card. Self-hostable, with an EU-hosted region.
Explore the PlatformOpen source, built in Europe
EuLLM is open source (AGPL-3.0) and built in Milan by I3K Technologies. We train and benchmark on EuroHPC supercomputers Leonardo, LUMI and JUPITER. Built in Europe, yours to run anywhere.
Data sovereignty →
From open model to specialist, to production
Specialize
Forge fine-tunes and distills an open-weight model on your own data.
Evaluate
Held-out benchmarks measure accuracy before anything ships.
Publish
Hub versions it with a model card and a compliance card.
Run
Engine runs it anywhere — laptop, server, or edge.
Why EuLLM Engine
- ~10 ms
- per decision
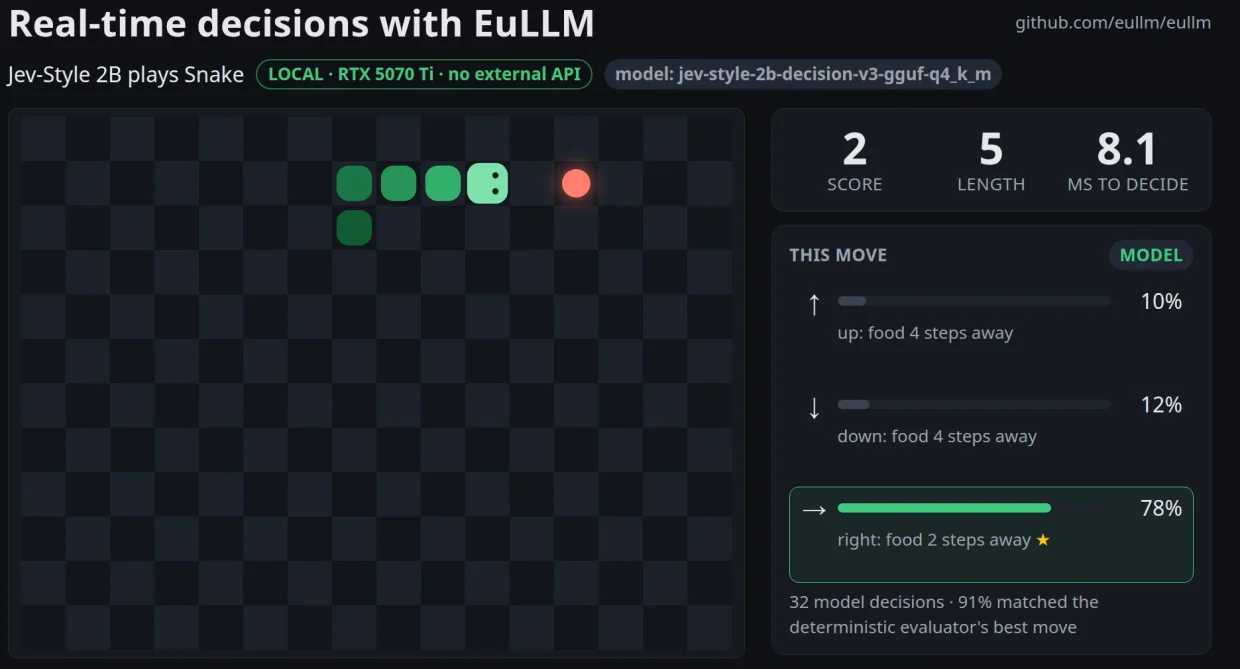
- 2B model deciding every Snake move on an RTX 5070 Ti
- 1,065 tok/s
- across 16 concurrent users
- on one RTX 5070 Ti, 8.1× a single request
- 10.8 tok/s
- 35B MoE, CPU only
- on a 20 W ARM board (Radxa Orion O6)
- CUDA · ROCm · Vulkan · Metal · CPU
- Runs everywhere
- one engine, every backend
Private by default
Prompts, documents and answers never leave your machine. No telemetry, no external API.
Drop-in replacement
Ollama and OpenAI APIs on port 11434. Open WebUI, LangChain, n8n and any OpenAI client work unchanged.
Fast where it counts
Continuous batching, quantized KV cache for long contexts, large MoE models on small GPUs.
Decisions, not just text
/v1/systemone reads the probability of every option straight from the model: structured decisions in milliseconds, for routing, triage and agents.
Runs anywhere
Laptop, workstation, on-prem server, edge device, private cloud. One binary, no Python, no Docker required.
Audit trail built in
Every request is logged locally in a file you control, ready for your auditors.
A chat UI is built in, at localhost:11435.
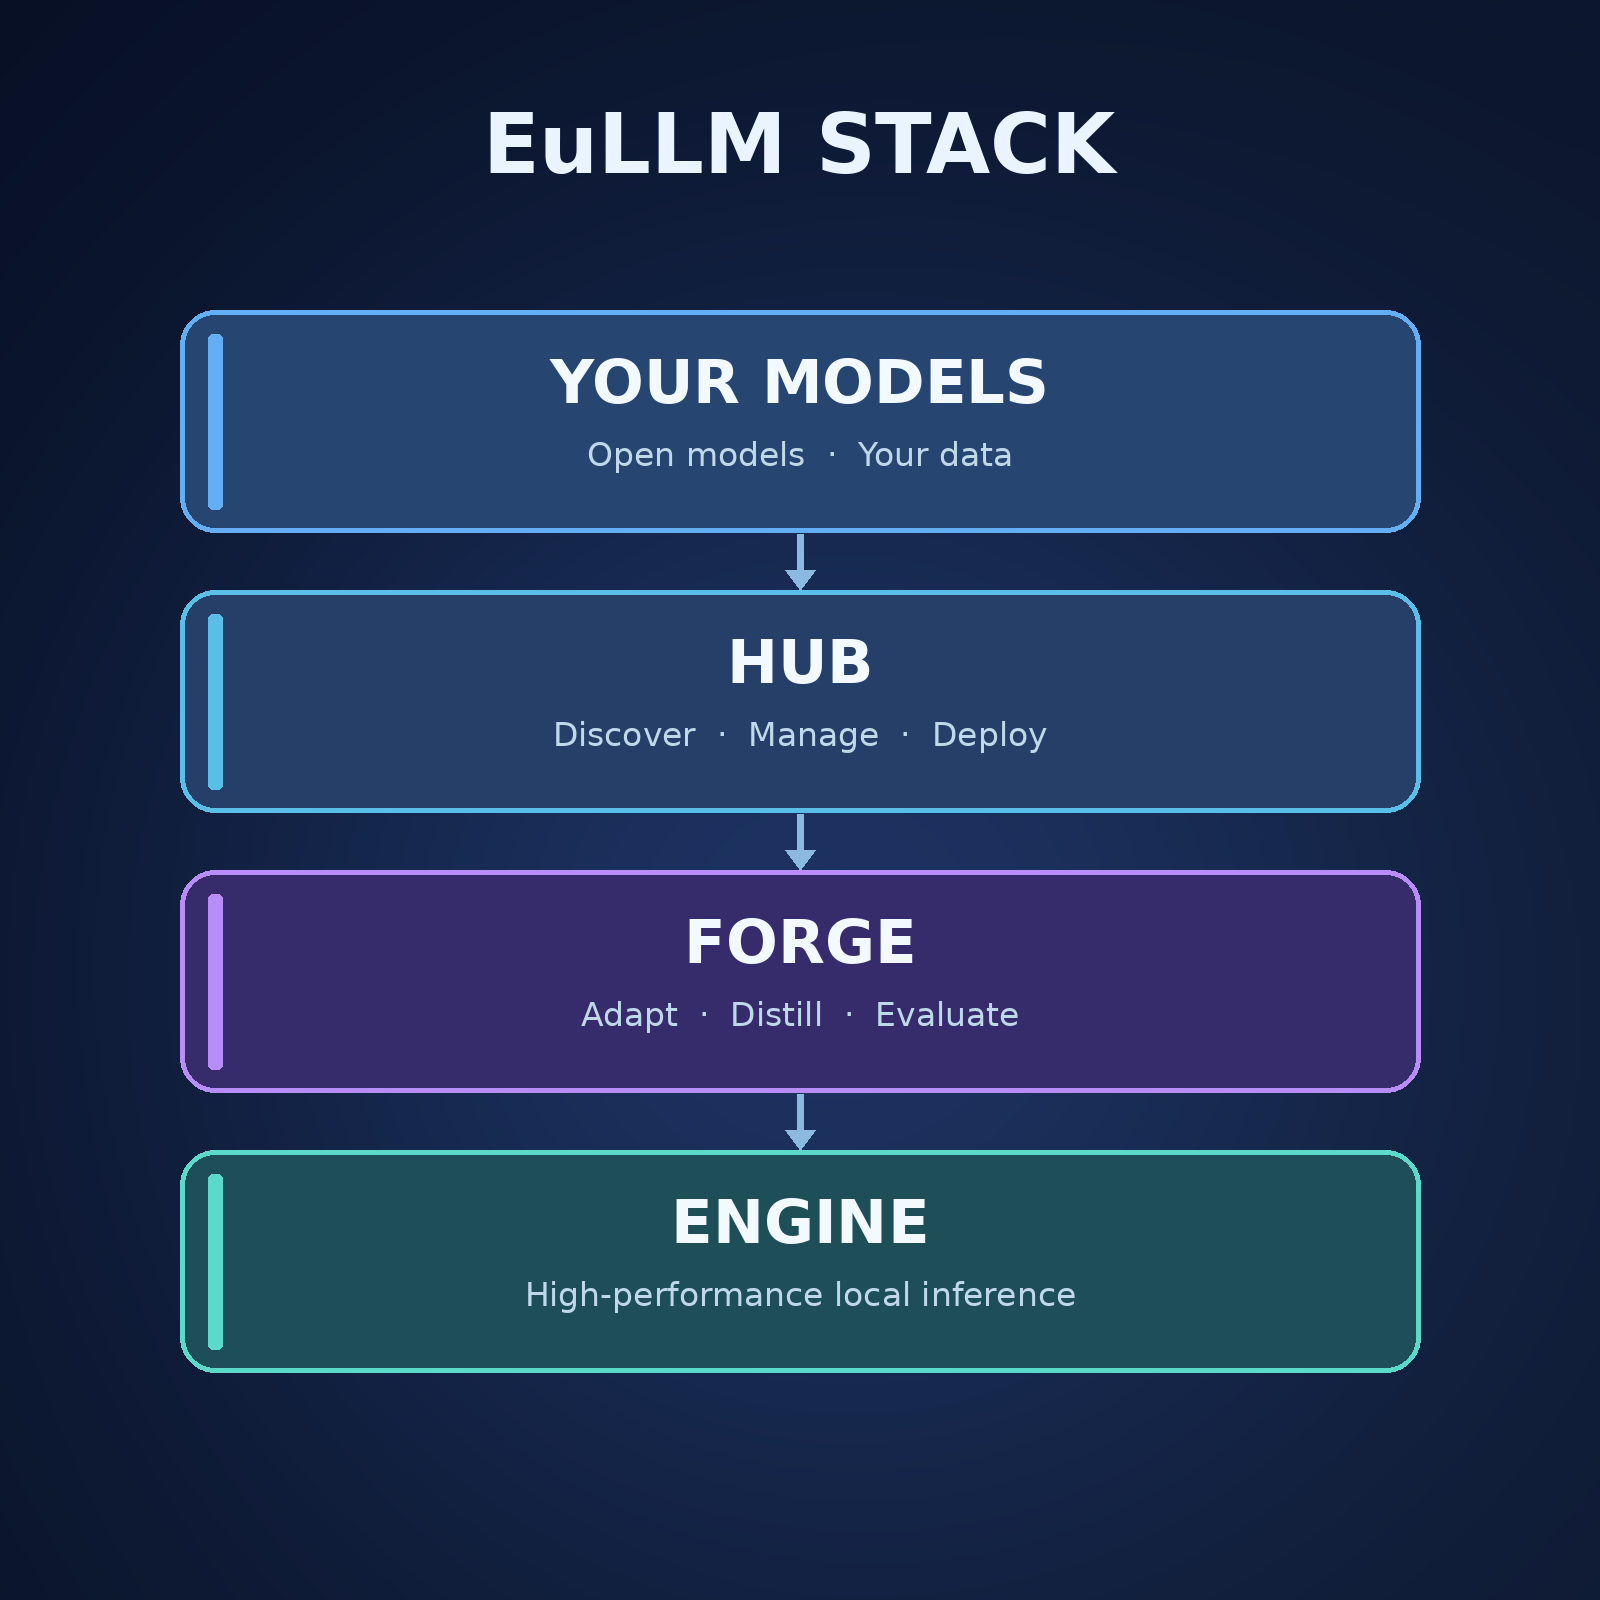
One stack, three layers
Specialist models you own, built on an open platform, served by a runtime that runs anywhere.
Your models
Specialized, evaluated, and yours to run — GGUF files you own outright.
Hub — distribute
PrototypePublish, version and discover models, each with a model card and a compliance card. Self-hostable, with an EU-hosted region.
Forge — specialize
In developmentFine-tune, distill and evaluate open models on your data. Small specialists that answer precisely from your documents and sources, exported as a GGUF you own and run on Engine.
Engine
Runs any GGUF model, on any hardware, with zero telemetry.
Published: legal-it-4b and legal-it-8b for Italian law, evaluated on 429 held-out questions.
Open source. Run by you. Improved by everyone.
Open, everywhere you already work
EuLLM plugs into the tools and infrastructure you already use.

GitHub
Open source, AGPL-3.0. Every line auditable.
Hugging Face
Published specialist models, ready to download.
I3K RAG Engine
Retrieval system built for EuLLM's specialist models.
EuroHPC
Trained and benchmarked on Leonardo, LUMI and JUPITER.
Built for regulated work
Legal, healthcare, finance and public administration can't hand their data to someone else's API. EuLLM runs entirely on infrastructure you control, logs every request locally, and ships model and compliance cards with every Platform model.
- Local audit trail for every inference
- Documentation support for the EU AI Act and GDPR
- Specialist models for legal, medical and financial work (legal first)
- EU-hosted Hub region for organisations that require it
No binary or compliance card alone makes a system compliant: compliance is a property of the whole system and its governance.
Latest articles
29 September 2026 · 6 min read
From Tokens to Decisions: Running a 2B Jev-Style Decision Model Locally with EuLLM
A 2B Jev-style Decision Model running locally with EuLLM makes real-time decisions in around 10 ms on an RTX 5070 Ti, with no external API.
Read more →
12 September 2026 · 5 min read
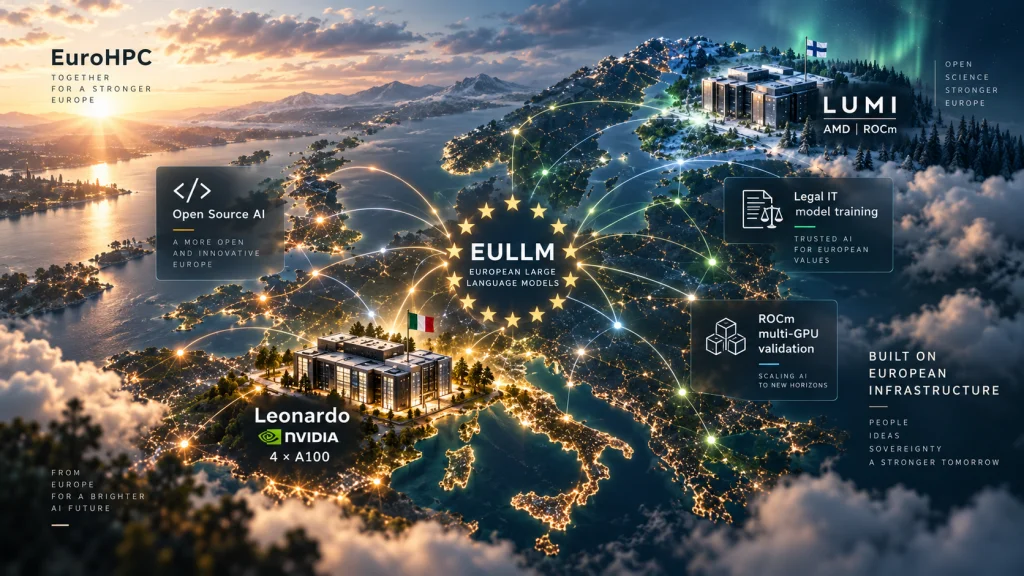
We Got Time on Leonardo and LUMI. Here's What We're Building.
EULLM has been allocated compute time on two EuroHPC supercomputers: Leonardo in Bologna and LUMI in Finland. We're building our first vertical model on A100s and validating ROCm multi-GPU on the continent's largest AMD cluster.
Read more →
Your models. Your infrastructure. Your data.
Install EuLLM Engine in one command, or talk to us about a specialist model for your domain.